Back to Stream
Database ArchitectureSeptember 14, 202695% synthesized
Why Database Benchmarks Are Only Useful When You Try to Break Them
Database benchmarks are often presented as objective truth, but they are actually architectural arguments that should be treated as experiments. The most valuable outcome of a performance test is not the winner, but the collaborative engineering effort that happens when competitors challenge and tune the methodology.
The Illusion of the Definitive Number. Performance benchmarks in the database world are frequently presented like scientific constants. Product A achieves a latency of 32 milliseconds, while Product B hits 98 milliseconds. The marketing conclusion is simple: Product A is three times faster. However, this interpretation is fundamentally flawed. A database benchmark is not a measurement of a static property, like the melting point of gold. Instead, it is a complex collection of architectural decisions disguised as a single number. These variables include hardware topology, storage types, memory allocation, indexing strategies, field mappings, query structure, cache state, concurrency models, compression algorithms, shard layouts, and ingestion tuning. Change a single one of these variables, and the performance profile often shifts dramatically. This does not mean benchmarks are useless. It means we should view them as experiments rather than scoreboards. When SereneDB recently introduced its SearchBench project and claimed a performance advantage over Elasticsearch using a billion-record OpenTelemetry workload, the industry reaction should not be to blindly accept or dismiss the result. The correct response is to attempt to break the benchmark. ## Benchmarks as Arguments, Not Facts. Every benchmark is essentially a persuasive argument. It is a set of constraints designed to reveal the strengths of one architecture while potentially minimizing the visibility of another. Consider the sheer number of configuration knobs available in modern distributed systems. In Elasticsearch, for example, the difference between a high-performance cluster and an underperforming one often comes down to internal settings like the refresh interval, heap sizing, query concurrency, and document values. If one product is allowed to operate under a finely tuned configuration that matches its strengths, while the competitor is tested using a generic or suboptimal setup, the benchmark is no longer measuring database performance. It is measuring configuration expertise. True benchmarking requires that every system be allowed to perform like itself. This means engineers must be able to adjust index mappings, shard counts, and merge states to represent how that database would perform in a real world production environment. If a benchmark prevents this level of granular adjustment, it stops being a technical comparison and starts being a curated advertisement.
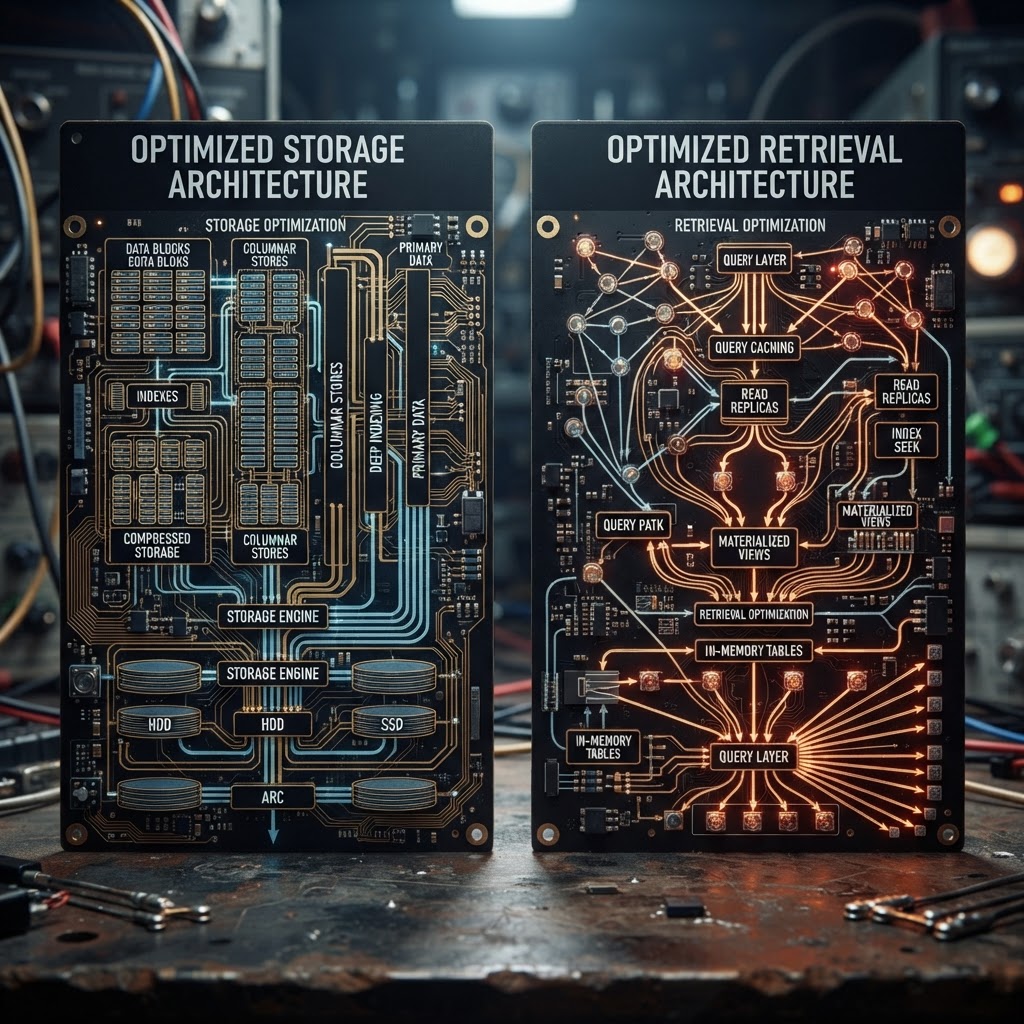
The Fallacy of Columnar Superiority. A common pitfall in recent database comparisons is the assumption that columnar storage is a magic bullet for performance. While column-oriented representations are exceptionally efficient for specific analytical tasks, such as scanning and aggregating subsets of data, they are not universally faster. Performance remains strictly tied to the workload. A system using a columnar engine might excel at large-scale aggregations, but it may struggle with ranked text retrieval, selective predicates, document reconstruction, or complex joins that fall outside its core strengths. The question is never whether columnar storage is inherently faster. The question is which execution path the query actually utilizes. When we strip away the marketing, we find that the most successful database systems are those that offer the most efficient execution paths for the specific data access patterns of the user. Benchmarking becomes marketing when it ignores these nuances to favor a specific architectural philosophy. ## The Evolution of Modern Workloads. The shift toward benchmarking using OpenTelemetry logs is a positive development because it reflects the reality of modern infrastructure. Modern search platforms are no longer just searching for keywords in a static index. They are increasingly required to handle complex, combined workloads that include full-text retrieval, time-range filtering, operational analytics, and metric aggregation. This has blurred the line between traditional search engines and relational-style analytics databases. When SereneDB promotes an engine capable of handling these mixed workloads without moving data between systems, they are engaging in a necessary architectural debate. This debate is significantly more important than any isolated latency number produced during a test. In an observability context, an engineer does not just search for an error message. They group failures by service, correlate trace data across a time window, and then dive into deeper analytical questions. The superior architecture is the one that minimizes friction across this entire investigative sequence, not necessarily the one that returns a single keyword search result the fastest. ## Reproducibility as the Ultimate Standard. The most promising aspect of SereneDB's SearchBench is its focus on reproducibility. By allowing competing database experts to modify adapters and improve configurations, the project invites external critique. This is how benchmarking should work. A high-quality benchmark must be designed to survive hostile review. If an engineer from a competing company can take the existing benchmark, tune their own system, and see the ranking change, that is a victory for the industry. It proves that the benchmark is working as a catalyst for deeper understanding. If, after rigorous tuning, the rankings remain the same, then the benchmark has successfully validated the relative strengths of the systems in a meaningful way. Either outcome is more valuable than a static bar chart. The goal should be to turn benchmarks into collaborative engineering exercises rather than advertisements. The database industry does not need fewer benchmarks. It needs benchmarks that are robust enough to withstand the scrutiny of the very engineers whose products are being measured. When we attempt to break a benchmark, we learn about the limitations and the capabilities of the underlying software. That is where real engineering progress begins.
Sources & Synthesis