Vector Data Tiering Strategy: Why Storing Embeddings in Hot Databases is Often a Financial Error
Engineering teams often make the mistake of storing all vector embeddings in high-cost, low-latency databases regardless of their actual query frequency. By adopting a tiered storage strategy, organizations can maintain long-term searchability while reducing infrastructure expenditures by nearly 90 percent.
Rethinking Vector Storage Paradigms
Vector search is frequently presented as an indexing challenge. Engineers spend weeks debating the merits of HNSW versus IVF algorithms, the optimal memory overhead, or the dimensionality limitations of their chosen database. While these concerns are valid for real-time recommendation engines, they often blind teams to a more fundamental issue: many vector stores are fundamentally over-engineered for the data they hold. The recent migration of 185 million sentence embeddings by Meltwater provides a compelling case study on why treating all vector data as hot, transactional assets is an architectural failure.
The Fallacy of Uniform Persistence
Most vector databases are built on OLTP (Online Transactional Processing) principles. They are designed for fast reads, rapid updates, and strict consistency. This makes sense for user-facing features where a vector represents a changing state, such as a user profile or a product description that gets frequently refreshed. However, when dealing with historical logs or vast corpora of LLM responses, these systems start to exhibit poor economics. In the Meltwater scenario, 97 percent of the database workload involved data that was append-only and rarely updated. By forcing this data to live alongside high-frequency transactional records, the company was essentially paying for millisecond-level retrieval speeds for information that only needed to be retrieved during analytical inquiries.
Time-Partitioned Indexing
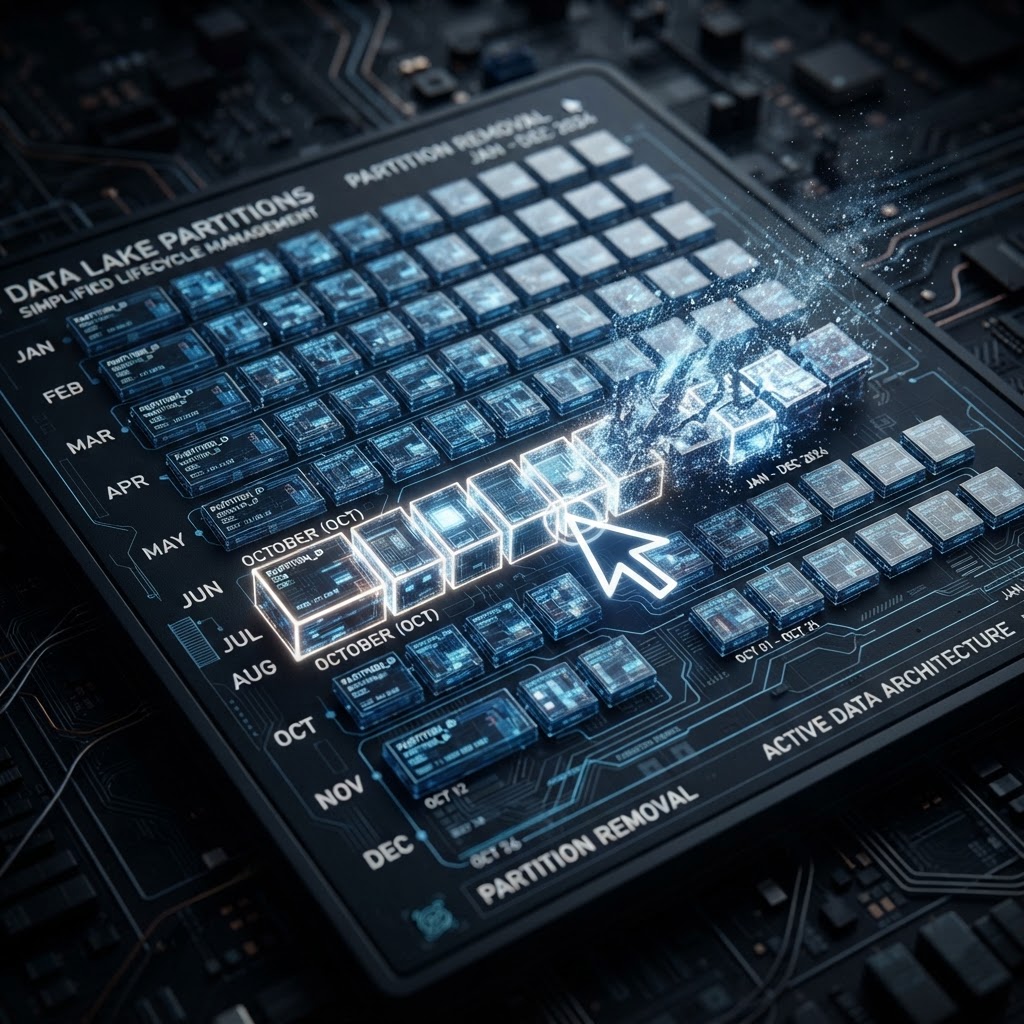
One of the most effective strategies for managing large-scale vector sets is time-based partitioning. By creating distinct indexes based on time intervals, such as monthly segments, developers gain granular control over the lifecycle of their data. This approach shifts retention from a complex deletion problem, where the database must perform massive tombstone operations to remove individual records, to a simple metadata operation. Dropping a month of data becomes a pointer removal task. Furthermore, this structure allows for model versioning at scale. If an organization updates its embedding model from version A to version B, they can start a new monthly index without the need for a massive, disruptive re-indexing job of the entire historical archive.
Building Resilience into Migrations
Moving hundreds of millions of embeddings carries inherent operational risk. The key to a successful transition lies in idempotency. By assigning deterministic keys to each vector based on its origin, such as a document ID and a specific sentence position, teams ensure that the ingestion process remains safe to retry. If a network partition occurs or a worker node crashes, the system can simply resume the write process without fear of duplicating records. This level of robustness is significantly more valuable than the specific choice of storage technology. A migration plan should include a dual-write phase, where the old and new systems receive identical data, followed by a shadow read phase to compare results. This turns the migration into a measurable engineering task rather than a hopeful launch.
Defining the Temperature Model for Embeddings
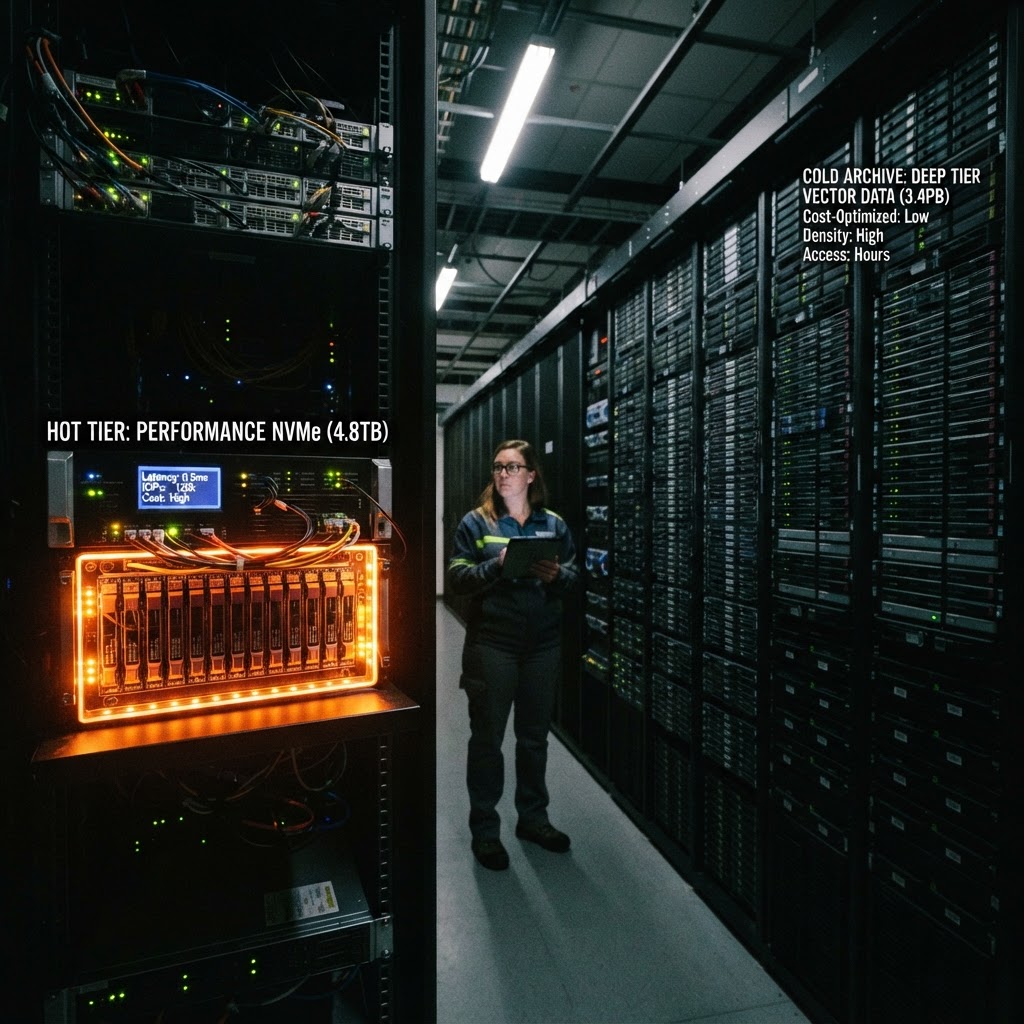
To optimize costs, engineers must categorize their vectors based on their access patterns, much like standard log management systems.
- Hot: Data that requires sub-millisecond retrieval, supports complex multi-tenant filtering, and experiences constant updates.
- Warm: Data that remains actively searched but tolerates slightly higher latency and infrequent updates.
- Cold (Searchable): Data that is append-only and accessed periodically for batch analytics or historical retrieval. Here, cost is the primary driver over latency.
- Archive: Data kept purely for compliance, where semantic search capability is stripped away to minimize costs.
By matching these tiers to the appropriate infrastructure, such as using specialized object-storage-native vector systems for the cold tier, companies can reclaim budget that was previously tied up in expensive, underutilized cluster memory.
The Evolving Landscape of AI Infrastructure
We are currently in a period of rapid innovation where the constraints of yesterday disappear overnight. Features like metadata pre-filtering, which allow search engines to discard irrelevant records before performing similarity calculations, were once considered advanced optimizations. Today, they are standard expectations for modern vector systems. This means that architects must adopt a mindset of constant re-evaluation. A workaround implemented today to deal with a limitation in an object-storage vector engine may be natively supported by the cloud provider in the next quarter.
Conclusion
Infrastructure economics in the age of AI requires moving beyond the default assumption that all data requires the same performance SLA. When organizations ignore the cost of storage, they inadvertently limit the lifespan of their intelligence. Meltwater proved that moving to cost-optimized infrastructure did not just save money, it enabled them to extend their search history by nearly two years. The future of AI systems is not just about the quality of the embeddings themselves, but about the strategic efficiency of where those embeddings live. Stop paying for speed you do not need, and start treating your vector archives as the valuable, long-term assets they are.