Semantic Search Is Really a Decision About Which Errors You Can Afford
This article challenges the idea that semantic search renders traditional lexical search obsolete, arguing that the choice depends on an application's tolerance for different types of retrieval errors. By analyzing whether a system requires exact identification or conceptual proximity, developers can better determine the appropriate search architecture for their specific needs.
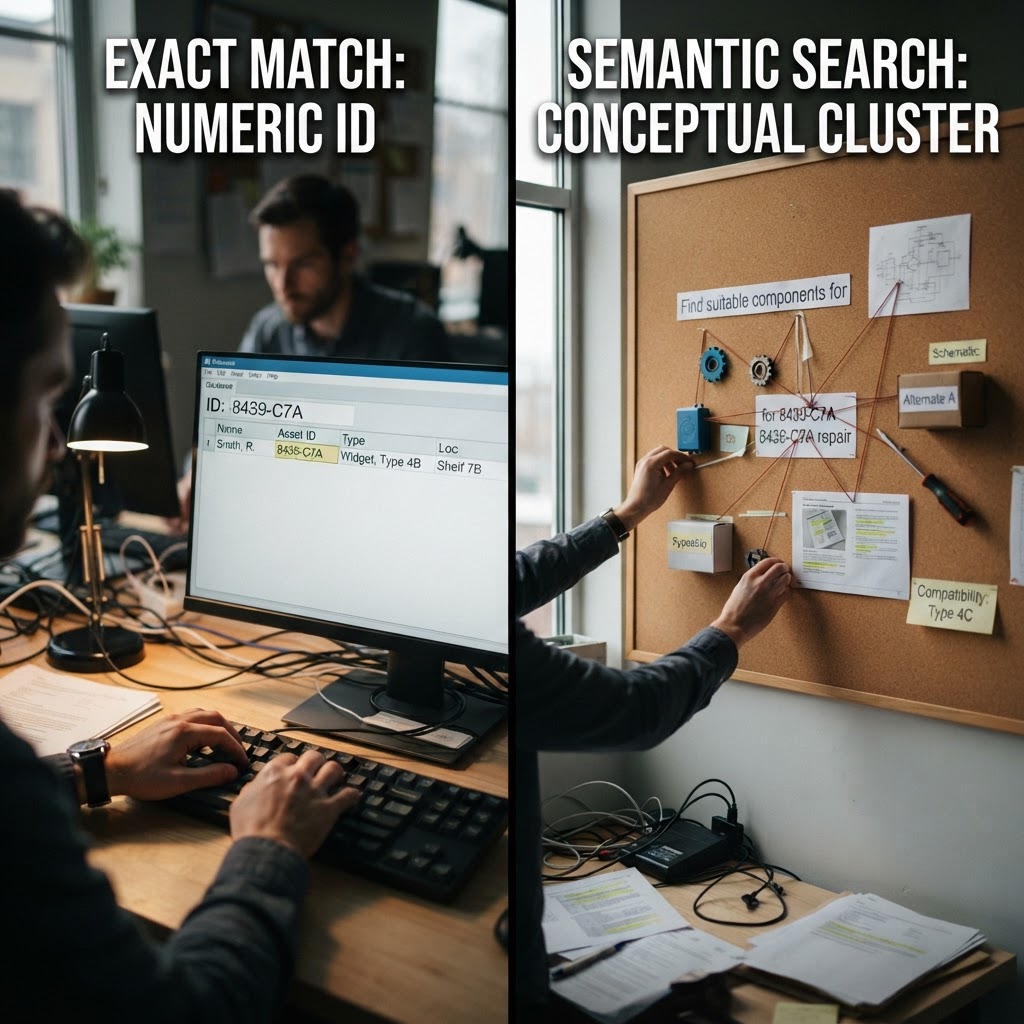
Semantic search is often presented as the successor to traditional text search. That framing is too simple. Vector databases and embeddings have changed what software can retrieve, yet they have not made exact search obsolete. In many applications, returning something conceptually similar when the user asked for something exact is not an improvement. It is an error. The more useful way to think about modern search architecture is not: Should I use lexical search or vector search? A better question is: What kind of mistake can this application tolerate? That decision tells you much more about the search architecture you need. Original article: https://stackoverflow.blog/2026/05/05/what-un-exactly-do-you-mean-by-semantic-search/?utm_source=iterable&utm_medium=email&utm_campaign=the-overflow-newsletter ## Search Has an Error Budget Too Engineers already think about error budgets in reliability. Search deserves a similar concept. Imagine two queries. The first is:
text Find event ID 3fa85f64-5717-4562-b3fc-2c963f66afa6 text Show me lightweight phones similar to an iPhone text dry arid text IP address UUID hostname hash error code username process name text The user never sees a relevant product. text The analyst investigates the wrong host. text Does identity matter? Does order matter? Does exact wording matter? Can related results be useful? What is the cost of a false match? What is the cost of a missed match? 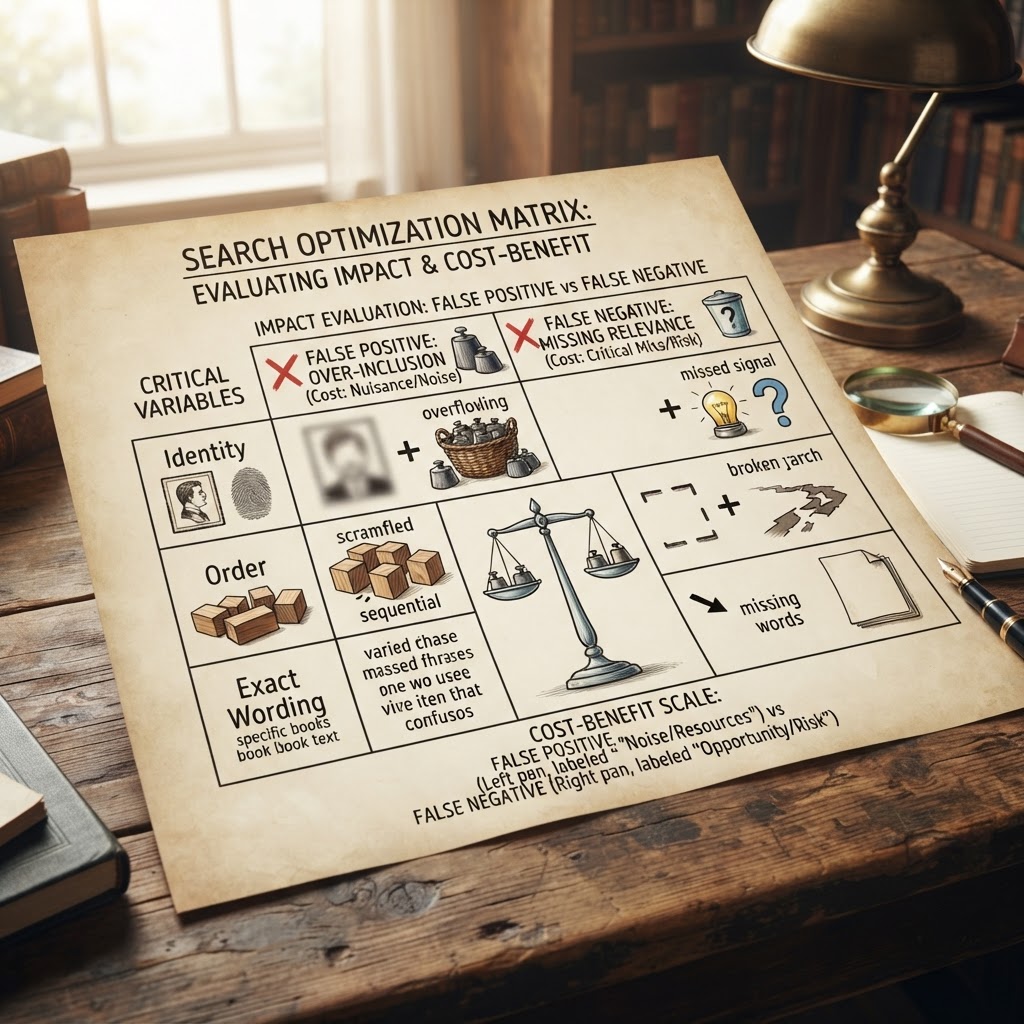
Hybrid Search Is Really Risk Allocation This leads naturally to a broader architectural insight. Many useful search systems do not need to choose one retrieval philosophy for every query. They can treat search methods as different instruments for different uncertainty levels. Exact retrieval can handle identifiers, names, filters, structured fields, and known terms. Semantic retrieval can expand recall around concepts. A ranking layer can decide how those results should interact. The real value of combining techniques is not that "hybrid search is modern." It is that different retrieval methods fail differently. One protects precision. The other expands meaning. A good system decides where each failure mode is acceptable. ## Retrieval Should Match the User's Intent, Not the Database Technology discussions frequently start from infrastructure: text We already run Elasticsearch. We already use Postgres. We need a vector database.
That puts the database before the retrieval problem. The better order is: text User intent ↓ Required retrieval behavior ↓ Acceptable errors ↓ Scale characteristics ↓ Architecture
A specialized vector service may make sense for one workload. A search platform with lexical and vector capabilities may fit another. A local vector index may be the right answer somewhere else. The correct architecture comes from the workload, not fashion. ## Scale Changes the Answer The Stack Overflow conversation spends considerable time on what happens when vector workloads grow. A technology that works comfortably at a small scale can become painful when vector indexes begin competing with transactional workloads or other services for memory and compute. The discussion uses pgvector as an example of something attractive at the beginning that may need separation later as vector workloads grow. That highlights another useful distinction. Search architecture has two questions: text Can this retrieve the right result?
and: text Can it keep doing that at the required scale?
Those questions should be evaluated separately. A prototype that answers the first tells you very little about the second. ## Embedding Quality Changes Database Behavior Vector search introduces another variable traditional search engineers may underestimate. The embedding model changes the geometry being searched. O'Grady points out that different embedding models create different vector-space structures, which can lead to different search characteristics under the same infrastructure configuration. That means performance is not purely a database concern. The representation itself affects the workload. Two systems can contain the same number of vectors, use similar infrastructure, and still behave differently if their embeddings form very different geometric distributions. This creates a tighter relationship between: text model choice retrieval quality index behavior latency infrastructure
Search architecture now extends into model architecture. ## Vector Search Makes Data Modeling Probabilistic Traditional databases train engineers to think in explicit structures. Rows. Columns. Terms. Fields. Keys. Embeddings introduce a different style of representation. Meaning becomes spatial. Two concepts are considered related partly through their relative positions in a high-dimensional representation. That changes debugging. When a SQL query returns the wrong row, engineers can often inspect the predicate. When semantic retrieval returns an odd result, investigation may involve: text embedding model chunking vector distribution distance metric index configuration query formulation ranking
That makes vector search powerful, yet less intuitively inspectable. Teams adopting it need operational practices that match that uncertainty. ## Relevance Testing Becomes More Valuable Semantic systems should not be judged only through latency and throughput. They need relevance evaluation. A vector query can return results in 20 milliseconds and still produce poor answers. Teams need representative query sets with expected outcomes. For example: text Query: "authentication failures after token rotation" Expected concepts: credential rotation expired secrets 401 errors identity provider failures
Then evaluate how changes to: text embedding model chunk size index settings reranking filters
affect retrieval quality. The search system now has something resembling a test suite. ## Local Vector Search Opens Another Architectural Path The discussion becomes particularly interesting when it moves to local search. O'Grady describes code search as a workload where sending a local repository to a remote vector service can create unnecessary network traffic and data movement. A local vector index can handle retrieval on-device, then synchronize selected context with a centralized system. That idea extends beyond code. A future agent may maintain local semantic indexes for: text documents email source code notes device history application context
and synchronize only the context that needs to move elsewhere. This creates a new architecture: text Local data ↓ Local embeddings ↓ Local retrieval ↓ Selected context ↓ Remote agent or model
That can reduce latency, bandwidth, and unnecessary data exposure. ## Agent Memory May Become a Search Problem The conversation ends with a more speculative idea: agents maintaining context across multiple devices through synchronized vector indexes. That points to a deeper issue. Long-term agent memory is not simply a storage problem. It is a retrieval problem. An agent may eventually possess years of historical context. The challenge becomes: text Which memory matters now?
Exact search alone cannot answer that well if the agent does not know the exact terms. Pure semantic retrieval can surface conceptually related memories yet miss exact identifiers. Agent memory may become one of the clearest cases for multiple retrieval strategies working together. ## Search Is Moving From Strings to Representations Traditional search operates largely on symbols people can inspect. Semantic search introduces representations people cannot interpret directly. That sounds like a technological shift. It is really an abstraction shift. Text is already a representation of meaning. Embeddings are another representation. Each preserves some information and discards some information. The architectural question is whether the information preserved by the representation matches the task. For product discovery, conceptual relationships may be exactly what matters. For security telemetry, losing an exact identifier can destroy the usefulness of the result. ## The Bigger Lesson Semantic search is sometimes discussed as though it makes lexical search old-fashioned. It does not. It changes the number of retrieval behaviors engineers can choose from. Exact search remains valuable where identity matters. Semantic search becomes valuable where conceptual proximity matters. Vector-native systems can become attractive where semantic retrieval dominates and scale grows. General-purpose search platforms remain attractive where workloads mix structured filters, lexical precision, analytics, and semantic retrieval. Local vector stores create another path for privacy-sensitive and agentic workloads. The architecture should follow the error model. That may be the clearest way to think about modern search: Do not start by asking which search technology is smarter. Ask what information your application cannot afford to lose. Then ask what kinds of related results it would benefit from discovering. Those two answers will tell you far more about whether the workload needs exact search, semantic search, or both. ### Original Source Ryan Donovan with Brian O'Grady, Stack Overflow, “What (un)exactly do you mean by semantic search?”, May 5, 2026. https://stackoverflow.blog/2026/05/05/what-un-exactly-do-you-mean-by-semantic-search/?utm_source=iterable&utm_medium=email&utm_campaign=the-overflow-newsletter
text We already run Elasticsearch. We already use Postgres. We need a vector database. text User intent ↓ Required retrieval behavior ↓ Acceptable errors ↓ Scale characteristics ↓ Architecture text Can this retrieve the right result? text Can it keep doing that at the required scale? text model choice retrieval quality index behavior latency infrastructure text embedding model chunking vector distribution distance metric index configuration query formulation ranking text Query: "authentication failures after token rotation" Expected concepts: credential rotation expired secrets 401 errors identity provider failures text embedding model chunk size index settings reranking filters text documents email source code notes device history application context text Local data ↓ Local embeddings ↓ Local retrieval ↓ Selected context ↓ Remote agent or model text Which memory matters now?