Back to Stream
AI InfrastructureSeptember 17, 202695% synthesized
OCR Architecture Evolution: Visual Data Ingestion as the New Retrieval Foundation
Document extraction is shifting from a simple text recognition utility to a structural intelligence layer that preserves semantic relationships for AI retrieval. This architectural pivot is essential for modern enterprises looking to unlock the latent value hidden within complex, non-linear document formats.
The Architectural Bottleneck of Text Extraction. For decades, Optical Character Recognition was treated as a terminal utility, a humble gateway through which physical documents passed to enter the digital realm. The implicit assumption was that once individual characters were identified and mapped to a string, the work was finished. This model assumed that the document structure was merely a decoration, a visual layer that could be discarded in favor of a raw, flattened stream of text. In the era of keyword search, this approach was sufficient. When the primary retrieval metric was the frequency of tokens, losing the distinction between a table cell and a footer had limited impact on search relevance. However, the paradigm has shifted toward Retrieval Augmented Generation, where the semantic integrity of the data determines the intelligence of the output.
Structure as Semantic Metadata. The primary failure of legacy OCR systems is the erasure of context. When a financial report is processed, the relationship between a header, a row label, and a numerical value is lost if the system treats the document as a continuous text stream. By utilizing advanced models like jina-ocr-v1, the extraction layer now preserves this structure through formats like Markdown, HTML, and LaTeX. This is not merely a change in output formatting, it is a transformation of the ingestion pipeline. A document now enters the index with its structural metadata intact, allowing embedding models to see a table as a structured object rather than a chaotic string of numbers. This allows the search system to maintain the integrity of the data hierarchy, which is essential for any downstream agent tasked with reasoning over enterprise records.
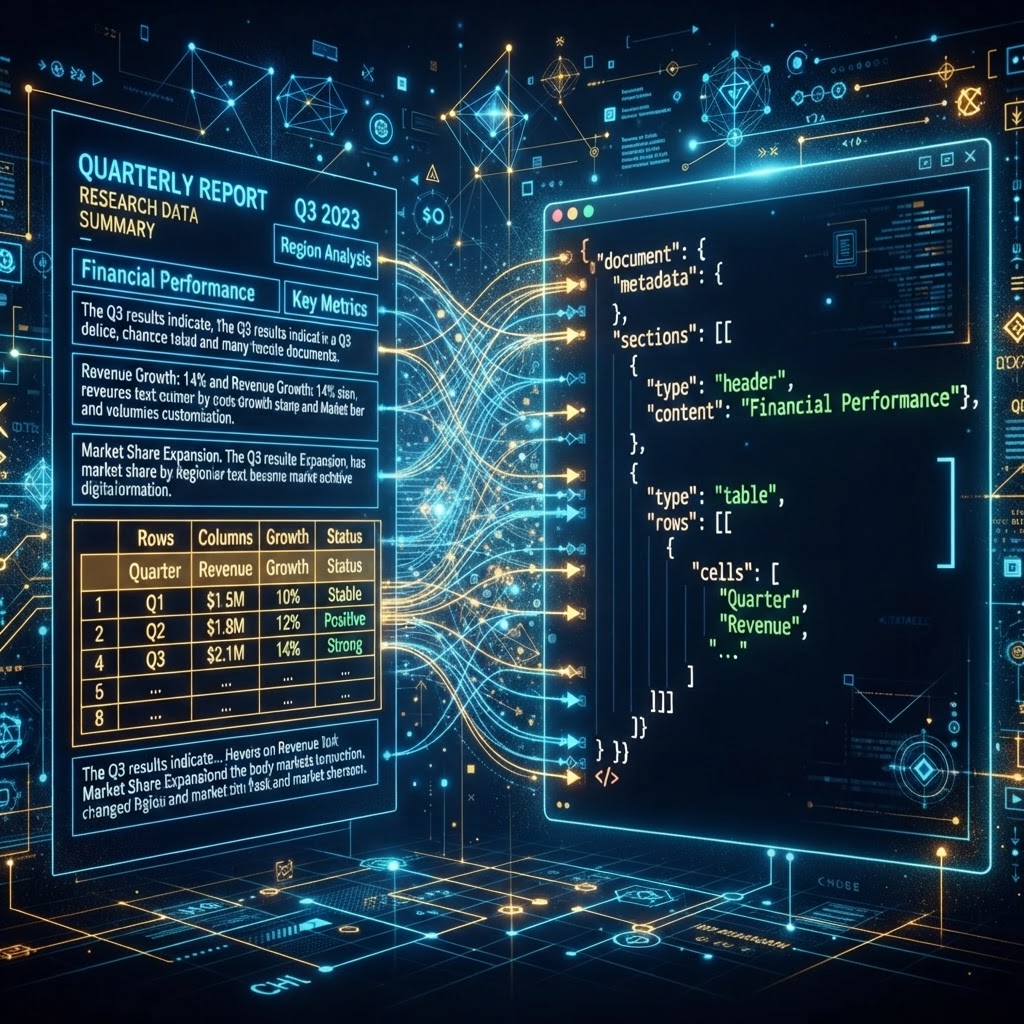
Efficiency Through Functional Specialization. The modern AI stack is moving away from the assumption that a single, monolithic model can solve every problem in the ingestion chain. Instead, we are entering an era of functional decomposition, where specialized architectures handle distinct stages of data processing. A document comprehension model, which understands spatial layout and visual context, is fundamentally different from a general-purpose reasoning model. By decoupling these tasks, organizations can optimize for performance and accuracy at each step. This approach reduces the load on reasoning models by providing them with cleaner, more accurate data structures. The specialization represented by jina-ocr-v1 illustrates a clear trend: the future enterprise stack consists of a highly efficient, tiered architecture where each component serves a precise purpose in the retrieval lifecycle.
The Hidden Cost of Retrieval Failure. When a RAG application produces a hallucination or an incorrect answer, engineers typically look for solutions in the late-stage components, such as embedding tuning or prompt engineering. This is a strategic error. A retrieval system is only as robust as the content it is given. If the extraction layer collapses a table of data into an incomprehensible block of text, no amount of reranking or vector search optimization can recover that lost information. We must treat document parsing as a fundamental component of search quality. If the source document is parsed incorrectly, the entire RAG pipeline becomes contaminated at the point of ingestion. Fixing the OCR layer is often the most cost-effective way to improve the quality of an AI-powered search system.
Multilingualism as an Architectural Simplifier. Global enterprises operate across borders and languages, yet many infrastructure setups rely on a fragmented patchwork of localized OCR tools. This creates significant technical debt and operational complexity. The emergence of broadly multilingual parsing models simplifies this architectural landscape by providing a unified pipeline for diverse data types. By handling dozens of languages within a single framework, organizations can drastically reduce the overhead associated with maintaining disparate pipelines for different document categories. The value of this shift lies in the reduction of complexity, which directly enables faster iteration on AI projects.
Conclusion: Upgrading the Ingestion Layer. The future of enterprise intelligence lies in the ability to derive structured knowledge from unstructured, visual data. We must stop viewing OCR as a commodity at the edge of the system and start treating it as the primary architect of our retrieval quality. By prioritizing structural fidelity and functional specialization, organizations can bridge the gap between static archives and dynamic, AI-ready data. The systems that win will be those that recognize that their retrieval performance starts the moment a document is scanned, not when the user submits a query.
Sources & Synthesis