Database-Native Search Shifts Architectural Gravity Toward Simplicity
The integration of advanced search capabilities directly into PostgreSQL marks a significant architectural pivot away from mandatory distributed search infrastructure. This evolution empowers developers to optimize for simplicity by keeping retrieval workloads close to transactional data until complexity requirements mandate a transition to specialized engines.
The Architectural Pendulum Swings Back
For nearly two decades, the standard architectural pattern for modern web applications has been defined by a rigid separation of concerns. Transactional data lived in a relational database, while search capabilities were offloaded to specialized engines like Elasticsearch or Solr. This bifurcation was born of necessity. Relational databases were built to ensure ACID compliance, prioritize consistency, and maintain relational integrity. Search engines were built to handle the chaotic nature of unstructured text, employing inverted indexes, tokenization, and complex relevance ranking algorithms that would have crippled a traditional database under heavy write load.
However, we are currently witnessing a contraction in this design pattern. With the release of extensions like PlanetScale's TIN, search functionality is migrating back into the core database. This shift is not merely a technical optimization; it represents a fundamental change in how architects view the lifecycle of application development. We are moving from a default assumption of complexity to a strategy of progressive enhancement.
The Hidden Tax of Distributed Search
To understand why this shift matters, we must acknowledge the significant tax imposed by the classic search-engine-as-a-sidecar architecture. Maintaining a secondary search index creates a sprawl of operational requirements. Developers must implement change data capture (CDC) pipelines, manage schema synchronization, handle eventual consistency conflicts, and ensure robust error recovery for data that fails to sync. When data exists in two places, observability becomes a nightmare; verifying the integrity of the search index against the source database is a persistent maintenance burden.
For startups and internal tools, this overhead often provides diminishing returns. When the requirement is simply to provide a search box for product descriptions or to filter support tickets, the cost of maintaining a full cluster of Elasticsearch instances is difficult to justify. By moving search into PostgreSQL, these applications eliminate the synchronization layer entirely, allowing developers to treat search results as just another set of rows joined with transactional data. This eliminates the 'stale data' window that plagues many distributed systems.
Native Identity and the Power of Co-Location
The architectural innovation found in tools like TIN lies in their embrace of the database's native reality. By utilizing the PostgreSQL ctid (the physical location identifier of a tuple), the index avoids the costly abstraction layer that maps external search IDs back to database records. In traditional search architectures, the search engine assigns its own document ID, which forces the application to perform a secondary lookup in the database once a search result is returned.
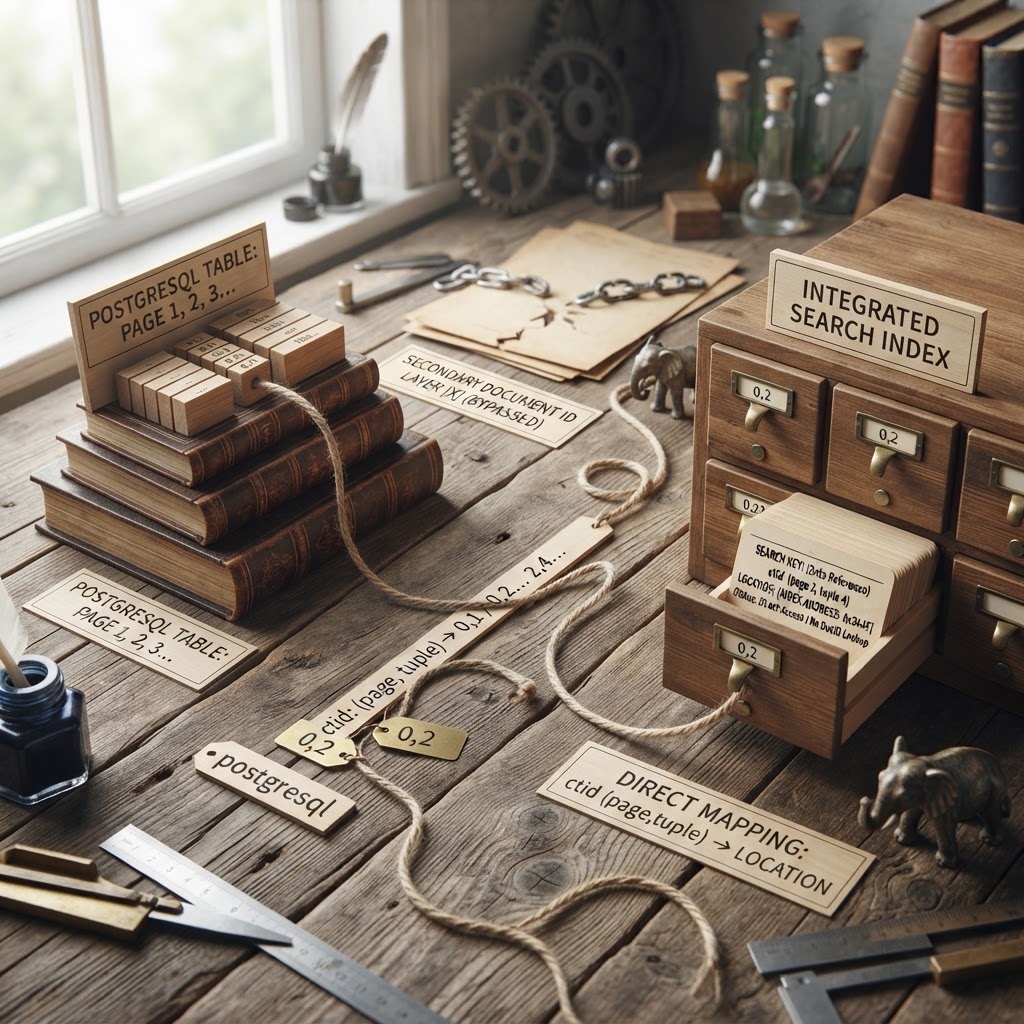
By aligning with the database's internal identity scheme, the search engine becomes an intrinsic component of the query planner. The database optimizer can now consider the relevance score provided by the search index alongside the filters applied by standard relational columns. This composability is the true game changer. A developer can write a single SQL query that filters by user permissions, joins against a profile table, and ranks by relevance in one execution plan. This prevents the classic 'n plus one' query pattern that occurs when fetching search results and then hydrating them with data from the database.
Navigating the Spectrum of Retrieval Needs
It is dangerous to view all search workloads as identical. The mistake many architects make is assuming that because a database can handle simple keyword lookup, it is a replacement for all search technology. This is a misunderstanding of the trade-offs. The spectrum of retrieval ranges from simple full-text queries to highly specialized, distributed enterprise search environments that require massive scale and complex AI-driven retrieval.
PostgreSQL-native search is ideally suited for the 'long tail' of application development, where the data volume is manageable and the search requirements are stable. However, as soon as you encounter signals such as search traffic scaling independently from write traffic, the need for complex, query-time relevance tuning, or the necessity of cross-cluster data aggregation, the specialized search engine becomes the correct tool again. The goal should be to push the boundary of what can be handled by the database, but to recognize the ceiling at which performance requires hardware isolation and horizontal scalability.
Reclaiming Architectural Autonomy
The most important takeaway from the current convergence of database and search technologies is the democratization of infrastructure choice. We are no longer forced into a 'database or search engine' dichotomy at the start of a project. Instead, we can start with the database as the source of truth and the source of truth's interface. If the workload grows, the transition to a specialized system is a migration problem, not an architectural mistake. By starting with integrated tools like TIN, teams avoid premature over-engineering. We are finally entering an era where we can scale our architecture at the same rate as our product, rather than paying the full cost of global-scale search infrastructure on day one.